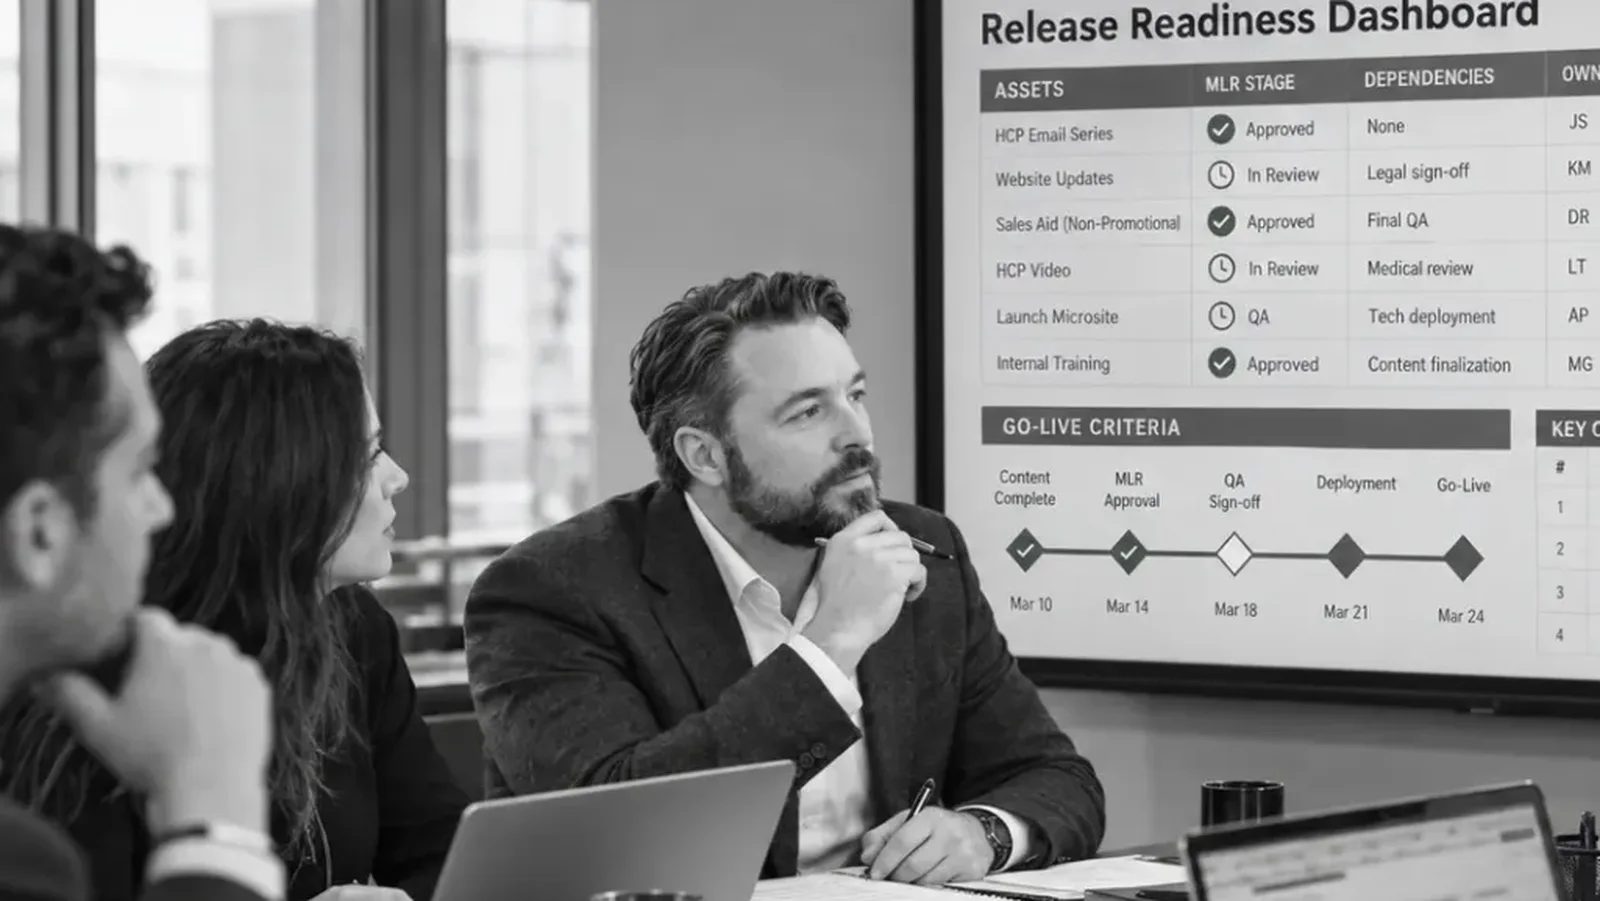
In 2024 and 2025, at Publicis Groupe, I led architecture and delivery of CoLab content automation for Comirnaty's $51 million global campaign. Medical, legal, and regulatory (MLR) review was the bottleneck across markets. I scaled a retrieval-augmented platform that checked every claim against approved sources, used Workfront to automate routing so each decision reached the right reviewer, and kept a complete audit trail.
Automating MLR review for Comirnaty's global campaign
- Azure + Google Cloud · Multi-tenant platform · RAG content automation · Human-in-the-loop MLR · $51M global campaign
- Technical program lead$51M campaign budget17 months
 Microsoft Azure
 Google Cloud
Challenge
A global campaign meant the same claims moving through MLR review in many markets at once. Review ran in multiple rounds, was tracked by email, and depended on which reviewer picked up the work. The same claim could be validated differently from one region to the next, prior approvals were not reused, and there was no traceable record of why a decision was made.
- One global campaign, many market teams
- Multi-round, email-tracked review
- No decision traceability or reuse of prior approvals
Same claim · Same reference · Four markets
Claim C-104 · Efficacy statement with supporting reference
| Market | Review rounds | Tracked in | Outcome |
|---|---|---|---|
| Market A | 3 | Email thread | Approved |
| Market B | 4 | Email thread | Revise wording |
| Market C | 2 | Shared tracker | Rejected |
| Market D | 5 | Email thread | Pending |
No record of why outcomes differed, and no reuse of the earlier approval.
Action
I led the platform from pilot to production across markets. Content is ingested, its claims are extracted, and each claim is checked against an approved claims library using retrieval-augmented generation. A confidence score then sets the review route and service level, from fast-track to senior review for novel claims, and Workfront automation creates the review task, assigns the reviewer and tracks each decision to approval in place of email.
The design choices were deliberate: assist reviewers rather than replace them, show claim-level evidence, escalate whenever the model is uncertain, and keep an immutable decision history. At launch every decision still went to a human reviewer, which built the trust needed for adoption. I mapped responsibilities across content, AI automation, medical, legal, regulatory, and brand teams for every stage from drafting to publication.
- Content ingestion
- Claim extraction
- RAG validation
- Confidence score
- Routing
| Confidence | Route | Review | Target |
|---|---|---|---|
| 95–100% | High confidence | Auto-approve eligible; human-confirmed at launch | Instant |
| 80–95% | Fast track | Expedited human review | Under 2 hours |
| 60–80% | Standard | Normal MLR queue | Under 24 hours |
| 0–60% | Senior review | Complex or novel claims | Under 48 hours |
Assist first: at launch every decision, including the auto-approve-eligible tier, went to a human reviewer with claim-level evidence and an immutable decision history.
Result
Outcomes reported by the Pfizer CoLab team: review cycle time for compliant content fell by 35%, content reuse rose 2.3 times, and more than 500 people used the platform. Every decision carried a complete audit trail, which became a regulatory asset rather than overhead.
Evaluation held the bar for scale: 96% citation faithfulness, 92.5% F1 on claim extraction, and p95 validation latency of 280 ms. The next improvements were already defined: suggest similar approved claims earlier, make regional rules configurable, and analyze false negatives sooner.
Reported outcomes
35%Faster review of compliant content
2.3×More content reuse
500+Platform users
Evaluation
| Metric | Result |
|---|---|
| Citation faithfulness | 96% |
| Retrieved document relevance | 91% |
| Claim extraction F1 | 92.5% |
| Compliance classification F1 | 90% |
| Recall@5 | 82% |
| p95 validation latency | 280 ms |
Reference architecture · Multi-tenant
CoLab: multi-tenant content automation with human-in-the-loop review
One shared platform serving every market in a global campaign as a separate tenant. Each market keeps its own approved claims library and review rules; shared AI services extract claims, validate them against that market's approved sources, and score confidence; and every decision routes to a human reviewer with an immutable audit trail. Labels show Azure and Google Cloud equivalents. See all four reference architectures.
Azure + Google Cloud · Shared control plane and market-isolated data plane
Global brand team
Core campaign assets
Global claims library
Brand guidelines
Publish
Market teams
Localized drafts
Translations
Market review rules
Submit
Prior approvals
Approved claims
Review decisions
Index
Control plane
Market onboardingTenant per market
Tenant catalogCosmos DB / Firestore
Identity providerEntra ID / Identity Platform · market claim
API gatewayRouting & quotas per market
Market-isolated data plane
Approved claims library
Per-market indexmarket_id filter
Market key
Decision history
Immutable logEvery decision
Evidence store
Vector searchAI Search / Vertex AI Search
Shared AI services
Claim extractionFrom each asset
RAG validationAgainst approved claims
Confidence scoringWith explanation
Model gatewayQuotas per market
Guardrails & evaluationFaithfulness, recall
Route
Validate
Review routing
Confidence tiersFast-track to senior review
MLR queueHuman decision
Route
Medical, legal & regulatory reviewers
Content workspace
Market workspaceEvidence beside each claim
Route
Content & brand teams
Operations & cost
Quality monitoring
Usage by market
Route
Platform & program leads
Cross-market governance
Attribute-based accessMarket in every token
Audit trailImmutable decisions
Policy as code
Noisy-neighbor quotas
Secrets management
Data residencyRegional deployments
Per-market monitoring
100%
Drag to pan · Ctrl/⌘ + scroll to zoomDrag to pan · Pinch to zoom
Control plane
Each market is onboarded as a tenant. The identity provider adds the market to every token, and the gateway routes and throttles by market.
Market-isolated data plane
Each market's approved claims library and decision history are kept apart; every query carries a mandatory market filter, and every decision is written to an immutable log.
Shared AI services
Claims are extracted from each asset and validated against that market's approved sources. A confidence score with an explanation sets the route; guardrails and evaluation hold quality.
Route & review
High-confidence claims go to fast-track review and novel claims to senior review. A human makes every decision, with the evidence beside each claim.
Cross-market governance
Application code, not the model, enforces market boundaries. The audit trail, quotas, and policy as code make isolation and every decision provable.