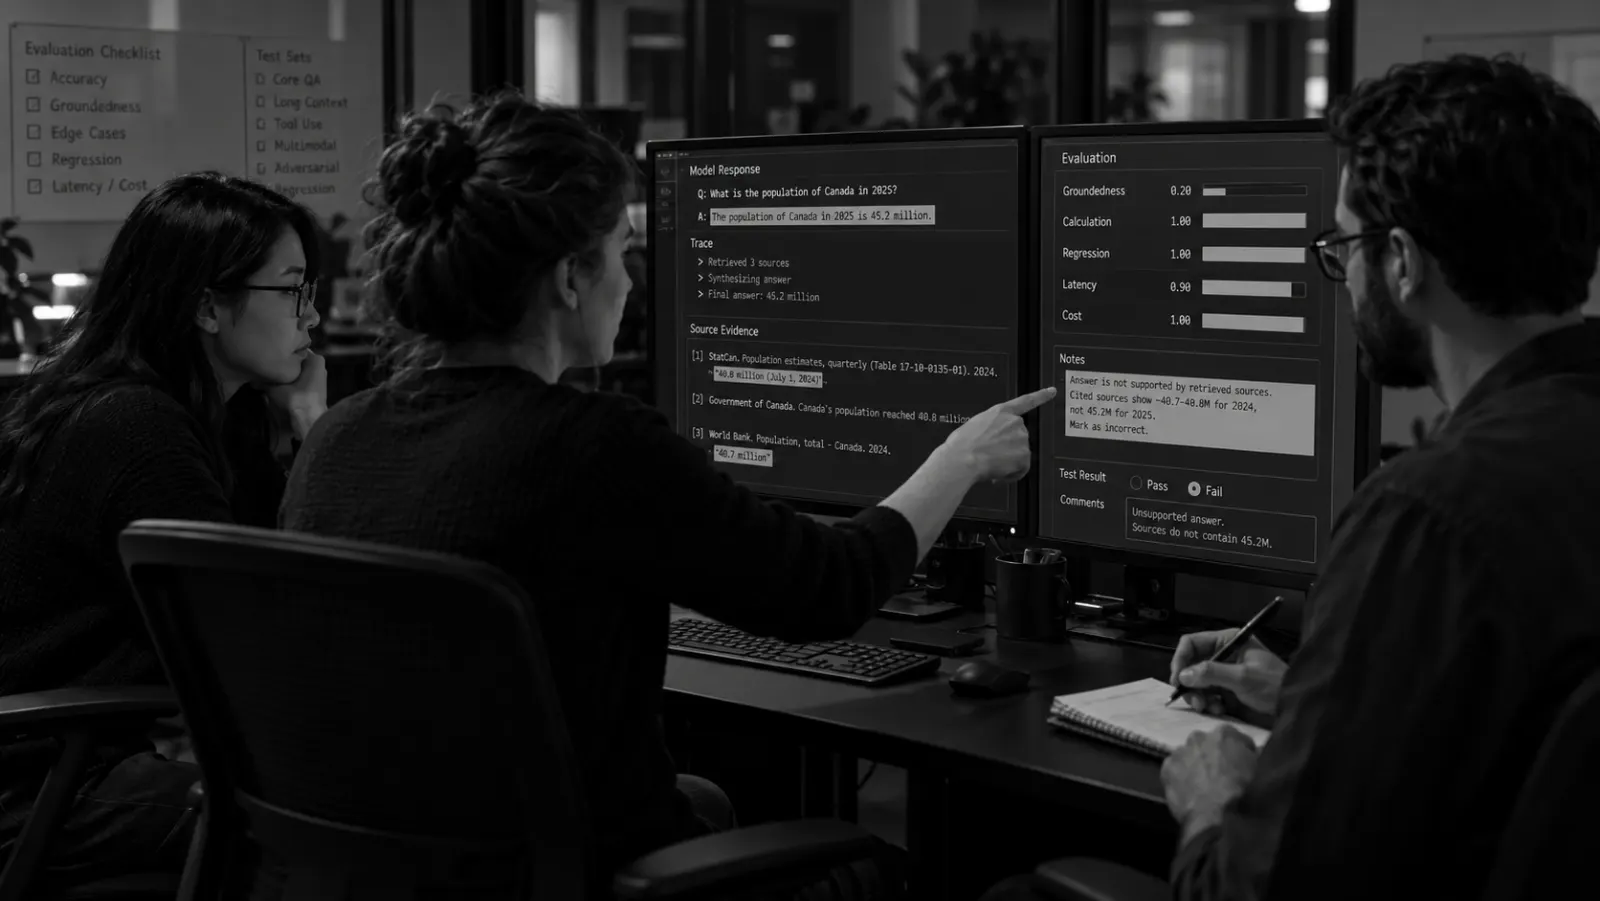
CoCo treats evaluation as part of the runtime contract rather than a review step after the fact.
CoCo · Verifier and Evaluation Agent Swarm
Challenge
Unsupported claims, calculation defects, missing citations, and regressions can all survive a conventional content review, because that review reads the output instead of testing it. For generated output the gap matters more: the same defect recurs at machine speed, and a reviewer who approves one version has no way to know whether the next one still holds.
Action
The design makes generated output carry enough evidence to be checked. Reference cases establish what a good answer looks like; role-specific evaluator agents review against their own criteria; deterministic checks catch what human judgment should not be asked to catch; evidence inspection exposes the source behind a claim; scoring thresholds decide what passes; and regression gates stop a fix in one place from breaking another. The AI Evaluation Scorecard is where those pieces meet — the harness is versioned, the thresholds are approved rather than assumed, and a failure routes to an owner instead of into a queue.
Result
The framework converts review criteria into executable checks, so quality becomes inspectable before release rather than argued after it. Benchmark results and captured regressions will provide the production proof. That evidence is still to come, and this is deliberately described as a capability designed rather than an outcome measured, not a result already banked.